Showing posts with label .value(). Show all posts

Saturday, June 26, 2010

More Fun With Hyperlinks: DDL Code

In my last blog entry, I demonstrated some queries that will produce results with hyperlinks to T-SQL Code. For example, the following query will find all procedures, views, triggers, and functions in AdventureWorks that contain the string ‘ContactTypeID’. The hyperlinks are created via the processing-instruction() XPath function. You can get a detailed explanation of how it works in my previous blog entry.

use AdventureWorks
go
select
ObjType=type_desc
,ObjName=schema_name(schema_id)+'.'+name
,ObjDefLink
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
cross apply (select ObjDefLink=(select [processing-instruction(q)]=ObjDef
for xml path(''),type)) F2
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
This produces the output below in the Grid Results window. Clicking on any of the hyperlinks will bring up the code for that object in a new window.

Object Query With Hyperlinks

Piotr Rodak (who has a very nice blog, and he also has, by far, the most clever blog name in existence) left a comment on my last post saying, “It’s a pity that table definitions cannot be acquired in a similar way.”

Wow, what a great idea! Imagine yourself walking into a new client (or new job) with a database with hundreds of tables and no documentation anywhere. Yes, you could right-click on the database in Object Explorer and choose Tasks -> Generate Scripts… from the popup menu and go through all the dialogs, and then generate a single code window or a single file or (if you have SQL2008) separate files for each object.

But instead, how about a query that produces a list of tables in the database, along with a hyperlink to the DDL Code for the table (and all its indexes)?

Coo-ul.

I was up for the challenge, and so I put a (looonngg) query together to do just that. Using the Object Catalog Views (i.e. sys.tables, sys.columns, etc), it generates the vast majority of the DDL Code for a table… the only features it leaves out are anything that has to do with Data Compression, Sparse Columns, Column Sets, FileStream, and Partitioning. Some things I left out because of time… other things I left out because they were SQL2008-only features and I wanted the query to work in both SQL2005 and SQL2008.

Here is the output of the query for the AdventureWorks database:

Query with Hyperlinks to DDL Code

And, if we click on the hyperlink for the HumanResources.EmployeeDepartmentHistory table, for example, we get the following (in an XML window):

XML Window Opened By Hyperlink

And to get the syntax coloring in a new code window, we perform a couple of keystrokes: CTRL+A (Select All), CTRL+C (Copy), CTRL+F4 (Close Window), CTRL+N (New Query Window), CTRL+V (Paste), and then a few DELETE keystrokes to get rid of the XML delimiters at the beginning and the end, and there’s the code for the creation of the table. Note the columns, their defaults, the check constraints, primary key constraint, foreign key references, and the (non-primary-key) index definitions for the table.

Code Window created from the XML Window

The code for this query is too long to incorporate here in this blog article, but you can download it from my SkyDrive. It’s just a single query, so you can easily incorporate it into a stored procedure if you wish.

Thanks again to Piotr for his comment that acted as the catalyst for this idea. I hope you find it to be helpful.

Thursday, June 17, 2010

Hyperlinks To T-SQL Code

There are often questions on the MSDN T-SQL Forum regarding how you can find all stored procedures (and/or functions and/or triggers and/or views) that contain a particular string. Thankfully, the object_definition() function gives us the ability to acquire the T-SQL code of those objects and we can easily find a particular search string in that code.

For example, the following query will look through all the objects (sys.objects) in the AdventureWorks database, looking for procedures (type=’P’) and views (type=’V’) and triggers (type=’TR’) and functions (types ‘FN’, ‘IF’, ‘TF’) that contain the string ‘ContactTypeID’:

select ObjType=type_desc 
,ObjName=schema_name(schema_id)+'.'+name
,ObjDef
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
I use a CROSS APPLY to introduce a column called ObjDef, which contains the full object_definition() value (i.e. the T-SQL code) of the object. This way I can reference ObjDef in my WHERE clause and in the SELECT list. And if I want to search for a second string, I can simply add a AND ObjDef LIKE ‘%otherstring%’ predicate to the WHERE clause.

I also sort the output so that the rows are grouped by the type of object and then, within each type, the rows are sorted by the name.

And that gives us the following result:

Boring Object Query

This is very nice to get this all at a glance, but the ObjDef column is limited. I can widen the column in the grid, but only so far. And the contents don’t contain any of the newline characters… it’s just one looonnngggg string of text that I can’t read. I could copy/paste the contents into Excel, but again, it will just be a single line of text with no newline characters. And even so, SSMS will not output any more than 65536 characters in a column in a grid result window, so we may not get the full code anyway.

We could output to a text window, which will retain the newlines, but the maximum characters per column that we can output is 8192. Plus the output is ugly.

So what can we do, outside of a lot of searching and pointing-and-clicking in the Object Browser, to see the code for these objects?

Well, MVP Adam Machanic had what I thought was a brilliant idea in how to accomplish this in his sp_who_is_active procedure. The answer is XML. XML columns have two great features. First of all, you can bump up the maximum character output of XML to be unlimited if you wish:

Query Options Dialog

And second of all, XML columns are conveniently presented as hyperlinks in Grid Output.

An unfortunate side-effect of converting text to XML, though, is that XML will encode characters like less-than and greater-than and ampersand to < and > and & respectively. But Adam cleverly uses the processing-instruction() XPath function, which will bypass the encoding and, more importantly, will preserve all the newlines and indentions exactly as is.

So here is a revised copy of our query to find ‘ContactTypeID’ in AdventureWorks, with a new column called ObjDefLink created via the processing-instruction() XPath function in a second CROSS APPLY:

select ObjType=type_desc 
,ObjName=schema_name(schema_id)+'.'+name
,ObjDefLink
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
cross apply (select ObjDefLink=(select [processing-instruction(q)]=ObjDef
for xml path(''),type)) F2
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
The processing-instruction(q) will put our object definition code between <?q … ?> delimiters, but, as I mentioned, it’s all presented as a hyperlink, as you can see below:

Exciting Object Query with Hyperlinks!

Let’s click on the hyperlink in the second row to see the code of the Purchasing.vVendor view in a new window:

XML Window Opened by Hyperlink

Looks great! I can see all the code for that view, but it’s in a drab gray color, since that’s how an XML window colors any processing-instruction tag.

If you prefer to see the code with all the usual syntax coloring in a T-SQL window, it’s just a matter of a few keyboard shortcuts: CTRL+A (to Select All), CTRL+C (to copy to the Clipboard), CTRL+F4 (to close the window), CTRL+N (to open a new query window), and CTRL+V (to paste the contents into that window). And then remove the <?q … ?> delimiters from the beginning and the end, and voila… there you see the code in all its glory:

Code Window created from the XML Window

This method can come in handy in several ways.

For example, rather than showing individual rows for the objects whose code contains a certain string, let’s instead just create a single hyperlink to ALL the code that contains the string. Here’s how:

declare @Script nvarchar(max) 
select @Script=(select '
/*
'
+replicate('=',100)+'
'
+schema_name(schema_id)+'.'+name+' ('+type_desc+')
'
+replicate('=',100)+'
*/'
+ObjDef+'
GO
'
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,type_desc
,schema_name(schema_id)+'.'+name
for xml path(''),type).value('.','nvarchar(max)')

select CodeLink=(select [processing-instruction(q)]=@Script
for xml path(''),type)
First, I populate a @Script variable, concatenating it with the code of each object, along with some comment header information I supply that contains the object’s name and its type, and I follow each code chunk with a GO command. (For an explanation of the FOR XML PATH and TYPE and .value() stuff in the code, please see my blog post entitled Making a List and Checking It Twice).

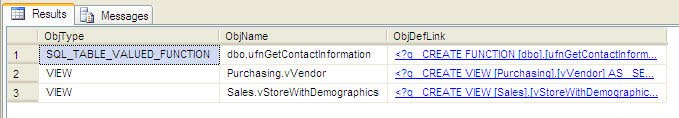
Then, the second query simply creates a single-row single-column processing-instruction XML link out of that variable. Here’s what the result looks like in the Grid Results window in SSMS:

Object Query to produce hyperlink to code of ALL objects

And when you click on that hyperlink, you get all the code (of all 3 objects… the function and the two views):

XML Window Opened by Hyperlink

And, again, with a quick CTRL+A, CTRL+C, CTRL+F4, CTRL+N, CTRL+V, and a couple DELETE keypresses, we get the code with syntax coloring, ready for examination and possible modification:

Code Window created from the XML Window

You can also incorporate these code hyperlinks into your DMV queries. For example, here is a query that I acquired from MVP Glenn Berry and tweaked a little bit to include a couple additional columns that I wanted, including the hyperlink column to the code. It uses DMV’s to look into the procedure cache and presents the top 50 queries in descending order of Average CPU time… in other words, the most expensive queries in terms of CPU:

select 
top 50 [Database]=coalesce(d.name,'AdHoc')
,CodeLink=(select [processing-instruction(q)]=qt.[text]
for xml path(''),type)
,TotWorkTimeMS=cast(qs.total_worker_time/1000.0
as decimal(12,2))
,AvgWorkTimeMS=cast(qs.total_worker_time/1000.0/qs.execution_count
as decimal(12,2))
,ExecCount=qs.execution_count
,[Calls/Second]=coalesce(qs.execution_count
/datediff(second,qs.creation_time,getdate())
,0)
,AvgElapsedTimeMS=cast(coalesce(qs.total_elapsed_time/1000.0/qs.execution_count,0)
as decimal(12,2))
,MaxLogReads=qs.max_logical_reads
,MaxLogWrites=qs.max_logical_writes
,CacheAgeMins=datediff(minute,qs.creation_time,getdate())
,QueryPlan=qp.query_plan
from sys.dm_exec_query_stats qs
cross apply sys.dm_exec_sql_text(qs.sql_handle) qt
cross apply sys.dm_exec_query_plan(qs.plan_handle) qp
left join sys.databases d on qt.dbid=d.database_id
order by AvgWorkTimeMS desc
And here is the result:

Most Expensive Queries

So the code that produced each of the high-CPU queries is just a click away.

I hope you find all this as useful as I do.

Update Jun26,2010: Check out my next blog entry, where I show how to provide hyperlinks to DDL (CREATE TABLE) code.

Wednesday, January 6, 2010

Delimited String Tennis (Again)… The Final Volley?

Delimited String Tennis Anyone?This is a continuation of my previous blog post, Delimited String Tennis Anyone?, which playfully talked about a virtual T-SQL Tennis match… a friendly rally back and forth between SQL Server MVP Adam Haines and myself in discussing methods of shredding comma-delimited strings in our blogs.

In my previous post, I expressed my disappointment with the following bit of code, which shreds elements from a comma-delimited string consisting of 5000 elements:

/* 
Note that I have to CAST() the first parameter of REPLICATE
in order to force it to produce more than 8000 bytes
*/
declare @CommaList varchar(max)
set @CommaList='ABC'+replicate(cast(',ABC' as varchar(max)),4999)

select x.i.value('.','varchar(3)')
from (select XMLList=cast('<i>'+replace(@CommaList,',','</i><i>')+'</i>' as xml)) a
cross apply XMLList.nodes('i') x(i)
This code, which I will call the “Derived Table Method”, took over 6 painful minutes to execute!

It had to do with how the XML column in the derived table was actually streamed and processed in small chunks as opposed to just immediately instantiating a normal, vanilla XML column.

My solution to this problem was to just create an intermediate XML variable and process it directly:

declare @XMLList xml
set
@XMLList=cast('<i>'+replace(@CommaList,',','</i><i>')+'</i>' as xml)

select x.i.value('.','varchar(3)')
from @XMLList.nodes('i') x(i)
This code, which I will call the “XML Variable Method”, was more like it… it took less than a second to execute… an improvement of over 2000%!

Since I wrote that blog entry, I received a few comments and e-mails that suggested some other approaches.

A person named “Mister Magoo” (no relation to the cartoon character voiced by Jim Backus in the 1950’s and 1960’s I’m sure) commented that the “Derived Table Method” could be improved dramatically just by adding a .query() to the XML column created in the derived table:

select x.i.value('.','varchar(3)')
from (select XMLList=cast('<i>'+replace(@CommaList,',','</i><i>')+'</i>' as xml).query('.')) a
cross apply XMLList.nodes('i') x(i)
He was correct! This also took less than a second! I suppose the theory here is that adding the .query() method forces the XML column to be instantiated immediately instead of bringing about the whole streaming nonsense.

This is excellent… it eliminates the step of having to create an intermediate XML variable… everything can be done in one single statement. It’s not quite as fast as the “XML Variable Method”, but we’re only talking about a small difference in milliseconds… it certainly performs like lightning.

The results of the above 3 methods come out as follows:

/*
Method CPU Duration(ms)
----------------------------------------------------
Derived Table 369,187 398,791
Derived Table with .query() 156 168
XML Variable 99 117
*/
I also got an e-mail from my friend SQL Server MVP Alejandro Mesa (some of you may know him as Hunchback on various SQL Forums), who mentioned that things could be sped up even more by changing the XQuery expression passed as the first parameter to the .value() method.

Instead of the simple ‘.’ that I passed…

select x.i.value('.','varchar(3)')
…Alejandro suggested using the .text() accessor and an ordinal [1] predicate, like so:

select x.i.value('(./text())[1]','varchar(3)')
True enough, this did improve the performance of the query. With this XQuery expression, we are indicating that we want the first instance ([1]) of the text-only node values (i.e. not any XML sub-elements) in our x.i node. This is more specific than our original ‘.’ expression, which indicated that we wanted to process the entire x.i node.

You can get a clearer idea of how these two XQuery expressions work in the following examples:

declare @XMLVar xml
set
@XMLVar='<a>abc<b>xyz</b>123</a>'

select x.i.value('.','varchar(10)')
from @XMLVar.nodes('a') x(i)
/* Returns 'abcxyz123' */

select x.i.value('(./text())[1]','varchar(10)')
from @XMLVar.nodes('a') x(i)
/* Returns 'abc' */

select x.i.value('(./text())[2]','varchar(10)')
from @XMLVar.nodes('a') x(i)
/* Returns '123' */
The @XMLVar variable above had two text nodes within the <a></a> element. In our original queries at the beginning of this article, each of the <i></i> elements contained only a single text node (and that’s why the expressions of ‘.’ and ‘(./text())[1]’ both produced the same result), and yet the expression ‘(./text())[1]’ was much more efficient and therefore faster because it was so much more specific in indicating what we wanted to process.

When I applied Alejandro’s suggestion to the queries, you can see how the CPU and Duration decreased even more:

/*
Method CPU Duration(ms)
----------------------------------------------------------------
Derived Table 369,187 398,791
Derived Table with .query() 156 168
Derived Table with .query() and text()[1] 130 159
XML Variable 99 117
XML Variable with text()[1] 76 77
*/
Alejandro also pointed me towards a very detailed technical article at Microsoft TechNet entitled Performance Optimizations for the XML Data Type in SQL Server 2005. If you do a lot of XML manipulation, this article looks like a must-read.

Thank you again to Mister Magoo and Alejandro for their contributions! With all of this knowledge, we can all now be the speed demons of delimited string shredding.

Saturday, December 12, 2009

Delimited String Tennis Anyone?

Tennis Anyone?SQL Server MVP Adam Haines and I have been going back and forth for months in our blogs on the subject of creating and splitting a delimited string… it’s been kind of a virtual T-SQL Tennis match… not a competition, but rather a friendly rally, knocking the subject back and forth, practicing our skills. Between the two of us, we’ve just about beaten the subject to death; however, I like to think that our collective research has been a win-win situation for the SQL Server community.

(If you’d like to look at these past articles, read Adam’s posts here, here, here, and here and read my posts and comments here, here, here, and here.)

In Adam’s latest volley a few days ago (which you can read here), he did some in-depth time tests on various methods of splitting a delimited string…. the XML approach using XPath and the .nodes() and .value() methods, the permanent Numbers table approach, and the approach using a TVF with a virtual table of Numbers.

His verdict was that the XML approach was a biiiiig disappointment when handling a comma-delimited string of many items, in one case performing over 200 times slower (!!) than the Numbers table approaches. Like Adam, I was a bit crestfallen. The XML method is the usual method suggested on the T-SQL forums for doing this sort of thing.

It is literally shocking how badly it performs.

Take a look at the following example, in which I create a variable that contains a comma-delimited list of 5000 items. Then it uses the XML approach to shred the list into a result set of 5000 rows:

/* 
Note that I have to CAST() the first parameter of REPLICATE
in order to force it to produce more than 8000 bytes
*/
declare @CommaList varchar(max)
set @CommaList='ABC'+replicate(cast(',ABC' as varchar(max)),4999)

select x.i.value('.','varchar(3)')
from (select XMLList=cast('<i>'+replace(@CommaList,',','</i><i>')+'</i>' as xml)) a
cross apply XMLList.nodes('i') x(i)
The task that we’re asking SQL Server to do is not that complicated, but do you want to guess how long this takes to fully execute on my system? Are you sitting down?

It takes over 6 minutes!

Really disappointing…

I had a lot of trouble accepting this. After doing several experiments, I finally figured out what was going on.

The problem lies in the derived table in the FROM clause, where we create a derived XML column via the CAST function.

It seems we are not really creating a complete column or value at all. Apparently we are inadvertently creating an XML stream, which sends small chunks of data to the .nodes() method and then the chunks get handed over to the .value() method to come up with our result… one chunk at a time.

On my system, when I execute the above code, I see nothing at all happen for about almost 50 seconds. Then the first 676 rows get spit out into the results window. After another 50 seconds or so, another similar-sized chunk of rows get spit out. This happens like clockwork until it spits out the final 5000th row over 6 minutes after I started the query.

You may recall in a previous post of mine where I said that an XML stream is processed in 2033-byte chunks. Well, 676 rows of 3 bytes (‘ABC’) each equals 2028 bytes. (I’m assuming that there’s a little tiny bit of overhead involved and that’s why we can’t squeeze in the 677th row). My comma-delimited string consists of 5000 items at 3 bytes each, coming to 15000 bytes. Divide that by 2033 bytes and you get 7.38, which is the number of chunks of data that get processed. Multiply that by 50 seconds per chunk, and you get… voila… 6.15 minutes.

Well, this must be all really exciting for you math nerds out there, but how does it help us?

It does help to explain what’s going on, and it does show us that streaming the XML is reeeeeaaalllly sloooooow.

So is there hope for the XML method?

YES! YES! YES!

This slow streaming only occurs when we are creating the XML to be processed via a derived table or CTE. What If we instead transfer our comma-delimited string into an actual XML variable and then process that variable, like so?:

/* 
Note that I have to CAST() the first parameter of REPLICATE
in order to force it to produce more than 8000 bytes
*/
declare @CommaList varchar(max)
set @CommaList='ABC'+replicate(cast(',ABC' as varchar(max)),4999)

declare @XMLList xml
set
@XMLList=cast('<i>'+replace(@CommaList,',','</i><i>')+'</i>' as xml)

select x.i.value('.','varchar(3)')
from @XMLList.nodes('i') x(i)
Believe it or not, this takes only 0.174 seconds!

In comparing the two pieces of code outlined in this article, here are the results:

/*            Derived     XML
Table Variable Percent
Measurement Method Method Improvement
--------------------------------------------
CPU 386,172 125 2989%
Duration(ms) 368,747 174 2019%
*/
So I’m happy to report that all is not lost for the XML method. It’s still a contender in the list-splitting competition, giving the Numbers table methods a run for their money… as long as it is implemented in a certain way.

Back to you, Adam…

UPDATE ON Jan06,2010: Please read the follow-up to this article in which I talk about some additional methods to speed the process up even further.

Friday, October 16, 2009

Un-Making a List (or Shredding of Evidence)

In my previous blog entry, I described in detail how you could use the FOR XML clause to create a column with a comma-separated list of entries acquired from rows in a table somewhere.

In this article, we will do the opposite… We will take a comma-separated list and “shred” the individual items into rows.

Let’s start by creating and populating a test table:

create table #CSVLists 
(
ID int
,Description varchar(30)
,CSVList varchar(200)
)
insert #CSVLists select 1,'Stooges' ,'Moe,Larry,Curly'
union all select 2,'Castaways','Gilligan,Skipper,Thurston,Lovey,'
+'Ginger,Professor,MaryAnne'
union all select 3,'Monkees' ,'Davy,Micky,Peter,Mike'
(Okay, I know you Gilligan’s Island fanatics are chomping at the bit to tell me that the Skipper’s name was Jonas and the Professor’s name was Roy. I know that… Don’t bother e-mailing me about it… save a virtual tree).

There is a handy .nodes() method which you can apply to an XML datatype that will shred it into relational data. So our first step is to convert our CSVList column into a valid XML representation of the data. We do that this way:

select ID
,Description
,XmlList
from #CSVLists
cross apply (select TagsList='<x>'+replace(CSVList,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
/*
ID Description XmlList
-- ----------- -----------------------------------------------------------
1 Stooges <x>Moe</x><x>Larry</x><x>Curly</x>
2 Castaways <x>Gilligan</x><x>Skipper</x><x>Thurston</x><x>Lovey</x>...
3 Monkees <x>Davy</x><x>Micky</x><x>Peter</x><x>Mike</x>
*/
The first CROSS APPLY surrounded each item in the CSVList with the tags <x></x>. And the second CROSS APPLY converted that into an actual XML datatype.

Now that we have an XML column, we can apply the .nodes() method to it. We will pass 'x' to the .nodes() method so that it knows the tag (<x></x>) to shred. And let’s take a look at that result:

select ID
,Description
,XMLNode
from #CSVLists
cross apply (select TagsList='<x>'+replace(CSVList,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
cross apply XmlList.nodes('x') F3(XmlNode)
/*
Msg 493, Level 16, State 1, Line 1
The column 'XmlNode' that was returned from the nodes() method cannot be used
directly. It can only be used with one of the four xml data type methods,
exist(), nodes(), query(), and value(), or in IS NULL and IS NOT NULL checks.
*/
Oops… This new XmlNode object we created is not something that we can actually look at or use directly. So, as the error message indicated, we will use the .value() method against that XmlNode object to pull out an actual VARCHAR(20) value:

select ID
,Description
,ListItem
from #CSVLists
cross apply (select TagsList='<x>'+replace(CSVList,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
cross apply XmlList.nodes('x') F3(XmlNode)
cross
apply (select ListItem=XmlNode.value('.','varchar(20)')) F4
/*
ID Description ListItem
-- ----------- ---------
1 Stooges Moe
1 Stooges Larry
1 Stooges Curly
2 Castaways Gilligan
2 Castaways Skipper
2 Castaways Thurston
2 Castaways Lovey
2 Castaways Ginger
2 Castaways Professor
2 Castaways MaryAnne
3 Monkees Davy
3 Monkees Micky
3 Monkees Peter
3 Monkees Mike
*/
Wow, it works!

But, as is often the case, you know there’s more. Just like I did in my previous blog entry, I’m going to do something to purposely trip things up. Let’s add a list of TV Networks:

insert #CSVLists
select 4,'Networks','ABC,NBC,CBS,FX,TNT,A&E'
And let’s try the same query:

select ID
,Description
,ListItem
from #CSVLists
cross apply (select TagsList='<x>'+replace(CSVList,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
cross apply XmlList.nodes('x') F3(XmlNode)
cross
apply (select ListItem=XmlNode.value('.','varchar(20)')) F4
/*
ID Description ListItem
-- ----------- ---------
1 Stooges Moe
1 Stooges Larry
1 Stooges Curly
2 Castaways Gilligan
2 Castaways Skipper
2 Castaways Thurston
2 Castaways Lovey
2 Castaways Ginger
2 Castaways Professor
2 Castaways MaryAnne
3 Monkees Davy
3 Monkees Micky
3 Monkees Peter
3 Monkees Mike
Msg 9411, Level 16, State 1, Line 1
XML parsing: line 1, character 56, semicolon expected
*/
Ouch! Once again, we’ve run into the problem with the way that XML encodes and decodes special characters like ampersand (&).

We cannot CAST something as XML if it has an ampersand as part of the data, because XML will try to interpret it as an entity that must end in a semicolon:

select Info=cast('<x>A&E</x>' as xml)
/*
Msg 9411, Level 16, State 1, Line 1
XML parsing: line 1, character 7, semicolon expected
*/
In order for it to be accepted, we have to encode that ampersand as follows, so that XML will understand it to represent an actual ampersand character:

select Info=cast('<x>A&amp;E</x>' as xml)
/*
Info
--------------
<x>A&amp;E</x>
*/
And, as we learned in my previous blog entry, we can then take the .value() of that to un-encode it:

select Info=cast('<x>A&amp;E</x>' as xml).value('.','varchar(10)')
/*
Info
----
A&E
*/
So in our shredding query, we have to FIRST encode any special characters in our CSVList column, and THEN we can successfully CAST it as an XML column.

One might be tempted to use multiple REPLACE() functions to convert all ampersands to &amp; and less-thans to &lt; and greater-thans to &gt;, but who knows what others characters are out there that will create problems? We already have a tool at our disposal that will encode the characters for us… the FOR XML clause.

select ID
,Description
,XMLEncoded
from #CSVLists
cross apply (select XMLEncoded=(select [*]=CSVList for xml path(''))) F0
/*
ID Description XMLEncoded
-- ----------- ---------------------------------------------------------
1 Stooges Moe,Larry,Curly
2 Castaways Gilligan,Skipper,Thurston,Lovey,Ginger,Professor,MaryAnne
3 Monkees Davy,Micky,Peter,Mike
4 Networks ABC,NBC,CBS,FX,TNT,A&amp;E
*/
We learned in my previous blog entry that we can eliminate tags being created by explicitly specifying a column a name of [*]. If we hadn’t done that, then we would end up with our lists surrounded by <CSVList></CSVList> tags. And we eliminated yet another tag surrounding our data by passing the empty string to FOR XML PATH. So our lists are really the same as they were originally, except for the special characters being automatically encoded for us.

Now we can incorporate that CROSS APPLY into our query:

select ID
,Description
,ListItem
from #CSVLists
cross apply (select XMLEncoded=(select [*]=CSVList for xml path(''))) F0
cross apply (select TagsList='<x>'+replace(XMLEncoded,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
cross apply XmlList.nodes('x') F3(XmlNode)
cross
apply (select ListItem=XmlNode.value('.','varchar(20)')) F4
/*
ID Description ListItem
-- ----------- ---------
1 Stooges Moe
1 Stooges Larry
1 Stooges Curly
2 Castaways Gilligan
2 Castaways Skipper
2 Castaways Thurston
2 Castaways Lovey
2 Castaways Ginger
2 Castaways Professor
2 Castaways MaryAnne
3 Monkees Davy
3 Monkees Micky
3 Monkees Peter
3 Monkees Mike
4 Networks ABC
4 Networks NBC
4 Networks CBS
4 Networks FX
4 Networks TNT
4 Networks A&E
*/
Ahhh… Success!

By the way, you may have noticed that the making and un-making (shredding) of these comma-delimited lists is like PIVOTing and UNPIVOTing. PIVOT converts rows to columns and UNPIVOT converts columns to rows. We have done something similar, except in making a list, we converted rows into a single column, and in shredding a list, we converted a single column into rows.

I’ll leave you with one final demonstration. Our #CSVLists table that we created had some comma-separated lists. What if we want to sort the items in the lists?

We would first shred the items into rows, and then, using the FOR XML logic we put together in my previous blog entry, we will re-assemble the lists and use an ORDER BY to sort them:

;with ShreddedLists as
(
select ID
,ListItem
from #CSVLists
cross apply (select XMLEncoded=(select [*]=CSVList for xml path(''))) F0
cross apply (select TagsList='<x>'+replace(XMLEncoded,',','</x><x>')+'</x>') F1
cross apply (select XmlList=cast(TagsList as xml)) F2
cross apply XmlList.nodes('x') F3(XmlNode)
cross apply (select ListItem=XmlNode.value('.','varchar(20)')) F4
)
select ID
,Description
,SortedCSVList
from #CSVLists
cross apply (select CSVStringXML=(select ','+ListItem
from ShreddedLists
where ID=#CSVLists.ID
order by ListItem
for xml path(''),type)) F1
cross apply (select CSVString=CSVStringXML.value('.','varchar(max)')) F2
cross apply (select SortedCSVList=stuff(CSVString,1,1,'')) F3
/*
ID Description SortedCSVList
-- ----------- ---------------------------------------------------------
1 Stooges Curly,Larry,Moe
2 Castaways Gilligan,Ginger,Lovey,MaryAnne,Professor,Skipper,Thurston
3 Monkees Davy,Micky,Mike,Peter
4 Networks A&E,ABC,CBS,FX,NBC,TNT
*/
I hope you have many hours of happy list-making and shredding activity. Until next time…

UPDATE ON Dec12,2009: Please read an important follow-up to this article in which I discuss some issues with the speed of the XML shredding method.