Friday, August 13, 2010

Taking A Hint

A new client of mine needed some performance tuning in several of his stored procedures. In most cases, it involved creating an appropriate index, or changing a table-valued function call to an equivalent inline TVF call, or just correcting the predicates in the WHERE clause to make it more SARGable. But there were a couple times when I could eke out even more performance by doing a little something extra.

And what “extra thing” did I give to those queries? I’ll give you a hint: I gave them a hint.

I Want It FAST

For example, there was one procedure that did a little calculation to come up with a particular date, and then it needed to pull out some information from some tables based on a 1-day date range from that date. It was something like this query in AdventureWorks:

declare @DesiredDateAtMidnight datetime = '20010709'
declare @NextDateAtMidnight datetime = dateadd(day,1,@DesiredDateAtMidnight)
select OrderID=h.SalesOrderID
,h.OrderDate
,h.TerritoryID
,TerritoryName=t.Name
,c.CardType
,c.CardNumber
,CardExpire=right(str(100+ExpMonth),2)+'/'+str(ExpYear,4)
,h.TotalDue
from Sales.SalesOrderHeader h
left join Sales.SalesTerritory t on h.TerritoryID=t.TerritoryID
left join Sales.CreditCard c on h.CreditCardID=c.CreditCardID
where OrderDate>=@DesiredDateAtMidnight
and OrderDate<@NextDateAtMidnight
order by h.SalesOrderID
/*
OrderID OrderDate TerritoryName CardType CardNumber CardExpire TotalDue
------- ---------- --------------- ------------- -------------- ---------- ---------
43728 2001-07-09 Southwest Distinguish 55553397232060 03/2007 3953.9884
43729 2001-07-09 United Kingdom ColonialVoice 77771647096870 03/2006 3756.989
43730 2001-07-09 Southwest Distinguish 55552313505236 09/2007 3756.989
43731 2001-07-09 Australia Vista 11114001441348 11/2006 3953.9884
43732 2001-07-09 Australia Distinguish 55557723662910 11/2007 3729.364
43733 2001-07-09 Northwest SuperiorCard 33338859457470 04/2008 3953.9884
*/
That particular query produces this (actual) execution plan (click on the plan to see the full-size image in a new window):

Original Query Plan

The optimizer decided to approach this by doing a Merge Join between the CreditCard table (which has 19118 rows) and the result of a Join of the Territory and the SalesOrderHeader tables. Note that it had to SORT the Territory/SalesOrderHeader data by CreditCardID so that it could do that Merge Join. And then, after that, it had to SORT the final data by SalesOrderID, because that’s what the ORDER BY clause of the query called for.

Note, also that the optimizer estimated that my WHERE clause would pull 2831.85 rows (out of a total of 31465) from SalesOrderHeader. How did it arrive at this figure? Since the @DesiredDateAtMidnight and @NextDateAtMidnight variables had values that were unknown to the query, it had to make assumptions. The optimizer assumes that equality-based predicates are 10% selective and inequality-based predicates are 30% selective. Since I had two inequality-based predicates, it assumed that together they would be 30% * 30% = 9% selective. And, sure enough, 31465 total rows * 9% = 2183.85 rows.

But the final result of the query was only 6 rows.

This is the situation that I was in with my client’s query. The optimizer grossly over-estimated how many rows it would find, and so it came up with a query that was efficient for handling that many rows. But I knew that a day’s worth of data from the particular tables that I was querying would produce about an average of 10 rows, not thousands of rows.

So I gave the optimizer a hint… specifically I gave it a FAST 10 hint, indicating that it should put together a plan that would return 10 rows as fast as possible. Adding OPTION (FAST 10) to the end of our query above produces this (actual) execution plan:

Query Plan With OPTION (FAST 10) Hint

Since the optimizer now knew that only 10 rows were estimated, it could put together a more appropriate plan for that small result. Note that there are Nested Loop Joins rather than a Merge Join and a Hash Join, and there are no more Sort operators, since the main driving table of the query is the SalesOrderHeader Clustered Index, which is already sorted by SalesOrderID.

I could have used the OPTION (RECOMPILE) hint instead, which would allow the optimizer to “sniff” the values of the variables and put together an appropriate plan based on their values, but that would involve having to recompile the plan from scratch every time this procedure was run, and therefore the plan would not go into the cache for others to use. The OPTION (FAST 10) plan, on the other hand, would be cached for others.

The Profiler statistics for the two queries are as follows:

/*
Description CPU Reads Duration QueryCost Relative%
-------------------------------------------------------------
No Hint Provided 63ms 889 288ms 0.9698090 96%
OPTION (FAST 10) 31ms 775 173ms 0.0450217 4%
*/
The CPU is so low for both queries that it’s really meaningless to compare them, but you can see that the Number of Reads and the Duration are lower by introducing the hint. The optimizer figured the second approach was much cheaper, but that’s mainly because, as far as it was concerned, it was comparing a 2184-row query to a 10-row query.

In my particular case with the client, the query was a bit more complicated, so the difference in CPU and Reads was much more dramatic. By adding the FAST 10 hint, the CPU was decreased by 60% and the Reads were decreased by 75%.

Using the FORCE

Another query that I wanted to tune incorporated an array-splitting (inline) table-valued function that used a Numbers table.

Let’s put together an example in AdventureWorks to illustrate what I was dealing with. First, create a Numbers table consisting of the integers from 1 to 1,000,000 and create a clustered index on it:

;with 
L0
(c) as (select 0 from (values (0),(0),(0)) x(c)) --3 Rows
,L1(c) as (select 0 from L0 a, L0 b, L0 c) --27 Rows (3x3x3)
,L2(c) as (select 0 from L1 a, L1 b, L1 c) --19683 Rows (27x27x27)
,L3(c) as (select 0 from L2 a, L2 b) --387,420,489 Rows (19683x19683)
,NN(n) as (select row_number() over (order by (select 0)) from L3)
select Number=isnull(convert(int,n),0) --Force it to be a "not null" column
into dbo.Numbers
from NN
where n<=1000000
go
alter table dbo.Numbers
add constraint PK_Numbers
primary key clustered (Number)
with (fillfactor=100)
Next, create an inline table-valued function that would use that Numbers table to split a comma-delimited list of integers:

create function dbo.ufn_SplitIntArray
(
@List varchar(max)
,@Delimiter varchar(10)
)
returns table
as
return
select
Item=convert(int,String)
from dbo.Numbers with (nolock)
cross
apply (select ItemPos=Number) F1
cross apply (select DelimPos=charindex(@Delimiter,@List+@Delimiter,ItemPos)) F2
cross apply (select String=rtrim(ltrim(substring(@List,ItemPos,DelimPos-ItemPos)))) F3
where ItemPos<=convert(int,len(@List))
and substring(@Delimiter+@List,ItemPos,1)=@Delimiter
You can see how this function is used in the example below:

select * 
from dbo.ufn_SplitIntArray('123,456,789',',')
/*
Item
----
123
456
789
*/
Now that we have that in place, we can see a query that makes use of this function. The following will take a list of TerritoryID’s and will list the SalesOrderHeader rows that are in those Territories, along with the Territory Description:

declare @TerritoryList varchar(max) = '2,3,5'
select h.SalesOrderID
,h.OrderDate
,t.TerritoryID
,TerritoryName=t.Name
,h.PurchaseOrderNumber
,h.TotalDue
from dbo.ufn_SplitIntArray(@TerritoryList,',') a
join Sales.SalesTerritory t on a.Item=t.TerritoryID
join Sales.SalesOrderHeader h on t.TerritoryID=h.TerritoryID
order by h.SalesOrderID
/*
SalesOrderID OrderDate TerritoryID TerritoryName PurchaseOrderNumber TotalDue
------------ ---------- ----------- ------------- ------------------- ----------
43659 2001-07-01 5 Southeast PO522145787 27231.5495
43660 2001-07-01 5 Southeast PO18850127500 1716.1794
43667 2001-07-01 3 Central PO15428132599 8095.7863
...
74193 2004-07-02 5 Southeast NULL 43.0729
74548 2004-07-13 5 Southeast NULL 38.675
75103 2004-07-31 5 Southeast NULL 44.1779
(1223 rows total)
*/
And here is the (actual) execution plan for that query:

Original Query Plan

Notice that Parellelism is involved in this plan. The optimizer figured our query was so expensive that it decided it was cheaper to spread the burden of the query across the 4 processors in my system.

As far as how to attack the query, the optimizer put together a plan that starts by scanning the SalesTerritory table and Hash Joins it with the SalesOrderHeader table, resulting in an estimated 24,832 rows.

It also scans the Numbers table, first satisfying the predicate of

where Number<=convert(int,len(@TerritoryList))
Since the optimizer has no idea what is in @TerritoryList, it makes an inequality-based assumption that the predicate will have a selectivity of 30%, and therefore it estimates that it will produce an estimated 1,000,000 * 30% = 300,000 rows. In reality, it only produced 5 rows.

Then it applies a filter to those rows to pull the positions of the comma-delimited numbers in @TerritoryList… in other words a filter to satisfy the predicate of

where substring(','+@TerritoryList,Number,1)=','
It estimates that those 300,000 rows will filter down to 9486.83 (I have no idea how it arrived at this 3.16% selectivity figure). In reality, it only produced 3 rows. Finally, the optimizer plans on storing those rows into a Spool for repeated access by the Nested Loops operator.

Now the Nested Loops operator will match up each of the estimated 24,832 rows with each of the estimated 9486.83 rows from the spool and will find the ones that satisfy this JOIN predicate (which is implied by incorporating our inline table-valued function in our query):

convert(int
,rtrim(ltrim(substring(@TerritoryList
,Number
,charindex(',',@TerritoryList+',',Number)-Number
)
)
)
) = SalesTerritory.TerritoryID
Since that’s an equality predicate, it assumes 10% selectivity, so it comes up with a final estimated result of 24,832 * 9486.83 * 10% = 23,557,700 rows for the final result. Wow! In reality, the Nested Loops will match 31,465 rows with the 3 rows in the spool (producing 94,395 matches) and end up only finding 1223 that satisfy the JOIN predicate (a selectivity of only 1.3%).

The bottom line here is that the optimizer got scared by that million-row table of Numbers and grossly overestimated how many values it would pull from that table and so put together a plan to most efficiently handle a final product of over 23 million rows. That’s why it started by processing the 31,465-row SalesOrderHeader table and spooled the estimated 9486.83 rows from the Numbers table that it would match up with each of those.

But we know that, in reality, our @TerritoryList will only consist of a small handful of comma-delimited values, so the plan should ideally start with the Numbers table, producing the positions of the values in @TerritoryList and, for each of those values, look them up in the SalesTerritory and then find the rows in SalesOrderHeader with that TerritoryID.

In other words, it should process the plan in exactly the order that I specified in the query:

from dbo.ufn_SplitIntArray(@TerritoryList,',') a
join Sales.SalesTerritory t on a.Item=t.TerritoryID
join Sales.SalesOrderHeader h on t.TerritoryID=h.TerritoryID
Well, there’s a hint for that! If we add an OPTION (FORCE ORDER) to our query, we end up with a completely new (actual) execution plan:

Query Plan With OPTION (FORCE ORDER) Hint

And here are the statistics that Profiler gives us in comparing the two plans:

/*
Description CPU Reads Duration QueryCost Relative%
----------------------------------------------------------------
No Hint Provided 1499ms 63,783 854ms 1167.11 27%
FORCE ORDER 141ms 3,660 314ms 3149.68 73%
*/
Nothing changed in what the optimizer estimates… it still thinks the query will produce 23 million rows. And it obviously thinks we’re completely insane to do a FORCE ORDER, because it estimates that the cost will almost triple by doing it this way. But you and I know better, and by introducing that hint, we decreased the CPU and Reads dramatically.

But this new plan still has Parallelism in it. The optimizer thought we needed it because it thinks the cost is so ridiculous that it will be cheaper to split up the query among the 4 processors in my computer. And, interestingly enough, it figures that by doing that split, it can introduce Sort operators to order the two main streams by TerritoryID and do a Merge Join, and then turn around and do a Sort on SalesOrderID for the final result.

Well, we know that our final result is not going to be that large… it’s certainly not going to be anywhere even close to 23 million rows! So let’s just get rid of the Parallelism. We’ll add one additional hint (MAXDOP 1) to our query in order to force it to only use one processor:

option (force order, maxdop 1)
Here’s the (actual) execution plan that results from that hint:

Query Plan With OPTION (FORCE ORDER, MAXDOP 1) Hint

See how simple that new plan is? Now how does that compare to the previous two plans?:

/*
Description CPU Reads Duration QueryCost Relative%
--------------------------------------------------------------------
No Hint Provided 1499ms 63,783 854ms 1167.11 12%
FORCE ORDER 141ms 3,660 314ms 3149.68 31%
FORCE ORDER, MAXDOP 1 31ms 741 175ms 5788.61 57%
*/
The optimizer thinks we’ve completely lost our mind, since it estimates the Cost is 5788.61… over 5 times more expensive than the plan it would have produced without hints. It’s probably snickering… laughing behind our backs and thinking, “Your stupid plan with hints will take over an hour and a half to run, but if you let me do my job, I can do it all in only 20 minutes!”

But that couldn’t be further than the truth. By introducing the hints, we reduced the CPU by 98% and reduced the Reads by 99%.

One More LOOPy Enhancement

But wait! We can even do better!

The plan still involves a Clustered Index Scan of the entire SalesOrderHeader table. If we can create an index on TerritoryID and INCLUDE the other columns required by the query, then we could SEEK into that index by TerritoryID rather than SCANning it.

So let’s create an index… Note that the TotalDue column in SalesOrderHeader is actually a computed column based on SubTotal and TaxAmt and Freight, so we have to INCLUDE those columns:

create index ix_Terr_iOrdDt_iPO_iTDue 
on Sales.SalesOrderHeader
(TerritoryID)
include (OrderDate,PurchaseOrderNumber,SubTotal,TaxAmt,Freight)
Now let’s run our query (with our two hints) and see if that index made a difference in the plan:

Query Plan With OPTION (FORCE ORDER, MAXDOP 1) Hint And New Index

Hmmm… the only thing that changed was that it was SCANning our new index rather than SCANning the Clustered Index. That improves the query somewhat, decreasing the number of reads, because our new index is smaller in terms of number of pages:

/*
Description CPU Reads Duration
-----------------------------------------------
No Hint Provided 1499ms 63,783 854ms
FORCE ORDER 141ms 3,660 314ms
FORCE ORDER, MAXDOP 1 31ms 741 175ms
Add New Index 31ms 232 172ms
*/
But we created that index to take advantage of the TerritoryID. We wanted it to SEEK into the index rather than SCAN the entire thing.

So another hint to the rescue!

This time we will tell the optimizer that we only want it to use LOOP JOINs. So here’s our new query with all the hints involved:

declare @TerritoryList varchar(max) = '2,3,5'
select h.SalesOrderID
,h.OrderDate
,t.TerritoryID
,TerritoryName=t.Name
,h.PurchaseOrderNumber
,h.TotalDue
from dbo.ufn_SplitIntArray(@TerritoryList,',') a
join Sales.SalesTerritory t on a.Item=t.TerritoryID
join Sales.SalesOrderHeader h on t.TerritoryID=h.TerritoryID
order by h.SalesOrderID
option (force order, maxdop 1, loop join)
And here’s the new (actual) execution plan that it produces:

Query Plan With OPTION (FORCE ORDER, MAXDOP 1, LOOP JOIN) Hint

Note that we now have a Nested Loops Join that now SEEKs into our new index. And the results?

/*
Description CPU Reads Duration
-----------------------------------------------
No Hint Provided 1499ms 63,783 854ms
FORCE ORDER 141ms 3,660 314ms
FORCE ORDER, MAXDOP 1 31ms 741 175ms
Add New Index 31ms 232 172ms
Add LOOP JOIN Hint 16ms 69 144ms
*/
Hah! So we’ve ultimately decreased the Reads by 99.9% from 63,783 down to a measly 69. That’s the way it should be with a straightforward query like this one.

Thank goodness for the existence of hints. They’re one more effective tool we can use to beat the optimizer into submission persuade the optimizer to form a plan that we know is best for our query.

Tuesday, July 27, 2010

Windows 7 + SQL 2008 = Aaaaarrrgggghhh!

I’m not heavy into technical stuff. Oh sure, I can whip out complicated T-SQL code in my sleep, but when it comes to lower-level operating system type stuff, I’m not that savvy. I’ve never installed Windows on a machine or formatted a hard drive in my life. My laptop will stagnate over the years with whatever version of Windows originally got installed on it.

So, anyway, I (finally) bought a new laptop a couple weeks ago. It came with Windows 7 Home Edition installed on it, but I wanted Windows 7 Professional, so I paid the geeks at Best Buy to install that for me. The computer’s disk also came pre-formatted with a tiny C: partition and an enormous D: partition. And I didn’t want to change all the (perhaps bad) habits I’ve acquired over decades, so I also paid them to format the drive into a single C: partition. They charged me more than I expected for these services, but I didn’t care, because I just didn’t want to be bothered.

So once the computer was ready, I brought it home and started the installations of software and moving stuff over from my old computer. Every software installation went just swimmingly… until I got around to installing SQL Server 2008.

I had the Developer edition and opted to install every service and feature, and it took a while. But when that thermometer bar was almost all the way filled, it gave me an error. I don’t remember now what the error was, but I thought, “Oh swell... That’s all I need.”

Of course, you cannot re-try an installation. If an installation fails, you have to uninstall it first (which takes about as long as the original installation) before you attempt another install.

So I went on the web and googled Windows 7 and SQL 2008. I came up with a nice writeup by Aaron Bertrand about it. Apparently SQL 2008 will install with errors, but you should be able to turn right around and just install SP1 without a problem. Okay, easy enough. I tried some of the suggestions mentioned in his blog post. I installed/uninstalled several more times but with no luck.

I even went so far as to do the slipstreaming stuff explained by Peter Saddow (incorporating the SP1 installation into the original installation files), and it still didn’t work after several more attempts.

I searched and searched and tried many things to no avail. I probably installed/uninstalled at least 20 times. (Of course, I eventually got smarter and didn’t try to install ALL the features… I just attempted to install only the Database Engine so that it didn’t take as long).

Finally, when I was ready to jump off a cliff (and with my family very upset at me for ignoring them in favor of my installation obsession), I happened to come across a thread at SQLServerCentral.

The solution was very simple, but really maddening.

Are you ready for this?

If your computer name is the same as your user account name, the installation will fail. That’s it. Pure and simple. End of story.

Huh? Can you believe this?

My computer name was BRAD and my user account name was Brad. Well, that means death as far as installing SQL Server 2008 is concerned.

So I changed my computer name to BRAD-PC (At this point I was tempted to call it something R-rated like #$@*!) and of course everything installed without a hitch. (And my slipstreaming stuff worked so that it was installed instantly as SP1).

So let this be a lesson to you if you buy a new computer and want to install SQL 2008:

DO NOT GIVE YOUR COMPUTER AND YOUR USER ACCOUNT THE SAME NAME!

Sheesh.

Thank God that nightmare’s over.

Saturday, June 26, 2010

More Fun With Hyperlinks: DDL Code

In my last blog entry, I demonstrated some queries that will produce results with hyperlinks to T-SQL Code. For example, the following query will find all procedures, views, triggers, and functions in AdventureWorks that contain the string ‘ContactTypeID’. The hyperlinks are created via the processing-instruction() XPath function. You can get a detailed explanation of how it works in my previous blog entry.

use AdventureWorks
go
select
ObjType=type_desc
,ObjName=schema_name(schema_id)+'.'+name
,ObjDefLink
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
cross apply (select ObjDefLink=(select [processing-instruction(q)]=ObjDef
for xml path(''),type)) F2
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
This produces the output below in the Grid Results window. Clicking on any of the hyperlinks will bring up the code for that object in a new window.

Object Query With Hyperlinks

Piotr Rodak (who has a very nice blog, and he also has, by far, the most clever blog name in existence) left a comment on my last post saying, “It’s a pity that table definitions cannot be acquired in a similar way.”

Wow, what a great idea! Imagine yourself walking into a new client (or new job) with a database with hundreds of tables and no documentation anywhere. Yes, you could right-click on the database in Object Explorer and choose Tasks -> Generate Scripts… from the popup menu and go through all the dialogs, and then generate a single code window or a single file or (if you have SQL2008) separate files for each object.

But instead, how about a query that produces a list of tables in the database, along with a hyperlink to the DDL Code for the table (and all its indexes)?

Coo-ul.

I was up for the challenge, and so I put a (looonngg) query together to do just that. Using the Object Catalog Views (i.e. sys.tables, sys.columns, etc), it generates the vast majority of the DDL Code for a table… the only features it leaves out are anything that has to do with Data Compression, Sparse Columns, Column Sets, FileStream, and Partitioning. Some things I left out because of time… other things I left out because they were SQL2008-only features and I wanted the query to work in both SQL2005 and SQL2008.

Here is the output of the query for the AdventureWorks database:

Query with Hyperlinks to DDL Code

And, if we click on the hyperlink for the HumanResources.EmployeeDepartmentHistory table, for example, we get the following (in an XML window):

XML Window Opened By Hyperlink

And to get the syntax coloring in a new code window, we perform a couple of keystrokes: CTRL+A (Select All), CTRL+C (Copy), CTRL+F4 (Close Window), CTRL+N (New Query Window), CTRL+V (Paste), and then a few DELETE keystrokes to get rid of the XML delimiters at the beginning and the end, and there’s the code for the creation of the table. Note the columns, their defaults, the check constraints, primary key constraint, foreign key references, and the (non-primary-key) index definitions for the table.

Code Window created from the XML Window

The code for this query is too long to incorporate here in this blog article, but you can download it from my SkyDrive. It’s just a single query, so you can easily incorporate it into a stored procedure if you wish.

Thanks again to Piotr for his comment that acted as the catalyst for this idea. I hope you find it to be helpful.

Thursday, June 17, 2010

Hyperlinks To T-SQL Code

There are often questions on the MSDN T-SQL Forum regarding how you can find all stored procedures (and/or functions and/or triggers and/or views) that contain a particular string. Thankfully, the object_definition() function gives us the ability to acquire the T-SQL code of those objects and we can easily find a particular search string in that code.

For example, the following query will look through all the objects (sys.objects) in the AdventureWorks database, looking for procedures (type=’P’) and views (type=’V’) and triggers (type=’TR’) and functions (types ‘FN’, ‘IF’, ‘TF’) that contain the string ‘ContactTypeID’:

select ObjType=type_desc 
,ObjName=schema_name(schema_id)+'.'+name
,ObjDef
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
I use a CROSS APPLY to introduce a column called ObjDef, which contains the full object_definition() value (i.e. the T-SQL code) of the object. This way I can reference ObjDef in my WHERE clause and in the SELECT list. And if I want to search for a second string, I can simply add a AND ObjDef LIKE ‘%otherstring%’ predicate to the WHERE clause.

I also sort the output so that the rows are grouped by the type of object and then, within each type, the rows are sorted by the name.

And that gives us the following result:

Boring Object Query

This is very nice to get this all at a glance, but the ObjDef column is limited. I can widen the column in the grid, but only so far. And the contents don’t contain any of the newline characters… it’s just one looonnngggg string of text that I can’t read. I could copy/paste the contents into Excel, but again, it will just be a single line of text with no newline characters. And even so, SSMS will not output any more than 65536 characters in a column in a grid result window, so we may not get the full code anyway.

We could output to a text window, which will retain the newlines, but the maximum characters per column that we can output is 8192. Plus the output is ugly.

So what can we do, outside of a lot of searching and pointing-and-clicking in the Object Browser, to see the code for these objects?

Well, MVP Adam Machanic had what I thought was a brilliant idea in how to accomplish this in his sp_who_is_active procedure. The answer is XML. XML columns have two great features. First of all, you can bump up the maximum character output of XML to be unlimited if you wish:

Query Options Dialog

And second of all, XML columns are conveniently presented as hyperlinks in Grid Output.

An unfortunate side-effect of converting text to XML, though, is that XML will encode characters like less-than and greater-than and ampersand to &lt; and &gt; and &amp; respectively. But Adam cleverly uses the processing-instruction() XPath function, which will bypass the encoding and, more importantly, will preserve all the newlines and indentions exactly as is.

So here is a revised copy of our query to find ‘ContactTypeID’ in AdventureWorks, with a new column called ObjDefLink created via the processing-instruction() XPath function in a second CROSS APPLY:

select ObjType=type_desc 
,ObjName=schema_name(schema_id)+'.'+name
,ObjDefLink
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
cross apply (select ObjDefLink=(select [processing-instruction(q)]=ObjDef
for xml path(''),type)) F2
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,ObjType
,ObjName
The processing-instruction(q) will put our object definition code between <?q … ?> delimiters, but, as I mentioned, it’s all presented as a hyperlink, as you can see below:

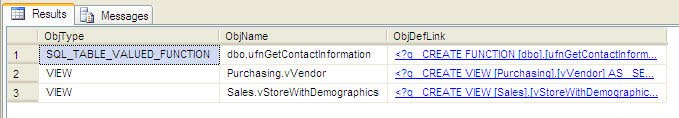
Exciting Object Query with Hyperlinks!

Let’s click on the hyperlink in the second row to see the code of the Purchasing.vVendor view in a new window:

XML Window Opened by Hyperlink

Looks great! I can see all the code for that view, but it’s in a drab gray color, since that’s how an XML window colors any processing-instruction tag.

If you prefer to see the code with all the usual syntax coloring in a T-SQL window, it’s just a matter of a few keyboard shortcuts: CTRL+A (to Select All), CTRL+C (to copy to the Clipboard), CTRL+F4 (to close the window), CTRL+N (to open a new query window), and CTRL+V (to paste the contents into that window). And then remove the <?q … ?> delimiters from the beginning and the end, and voila… there you see the code in all its glory:

Code Window created from the XML Window

This method can come in handy in several ways.

For example, rather than showing individual rows for the objects whose code contains a certain string, let’s instead just create a single hyperlink to ALL the code that contains the string. Here’s how:

declare @Script nvarchar(max) 
select @Script=(select '
/*
'
+replicate('=',100)+'
'
+schema_name(schema_id)+'.'+name+' ('+type_desc+')
'
+replicate('=',100)+'
*/'
+ObjDef+'
GO
'
from sys.objects
cross apply (select ObjDef=object_definition(object_id)) F1
where type in ('P' /* Procedures */
,'V' /* Views */
,'TR' /* Triggers */
,'FN','IF','TF' /* Functions */
)
and ObjDef like '%ContactTypeID%' /* String to search for */
order by charindex('F',type) desc /* Group the functions together */
,type_desc
,schema_name(schema_id)+'.'+name
for xml path(''),type).value('.','nvarchar(max)')

select CodeLink=(select [processing-instruction(q)]=@Script
for xml path(''),type)
First, I populate a @Script variable, concatenating it with the code of each object, along with some comment header information I supply that contains the object’s name and its type, and I follow each code chunk with a GO command. (For an explanation of the FOR XML PATH and TYPE and .value() stuff in the code, please see my blog post entitled Making a List and Checking It Twice).

Then, the second query simply creates a single-row single-column processing-instruction XML link out of that variable. Here’s what the result looks like in the Grid Results window in SSMS:

Object Query to produce hyperlink to code of ALL objects

And when you click on that hyperlink, you get all the code (of all 3 objects… the function and the two views):

XML Window Opened by Hyperlink

And, again, with a quick CTRL+A, CTRL+C, CTRL+F4, CTRL+N, CTRL+V, and a couple DELETE keypresses, we get the code with syntax coloring, ready for examination and possible modification:

Code Window created from the XML Window

You can also incorporate these code hyperlinks into your DMV queries. For example, here is a query that I acquired from MVP Glenn Berry and tweaked a little bit to include a couple additional columns that I wanted, including the hyperlink column to the code. It uses DMV’s to look into the procedure cache and presents the top 50 queries in descending order of Average CPU time… in other words, the most expensive queries in terms of CPU:

select 
top 50 [Database]=coalesce(d.name,'AdHoc')
,CodeLink=(select [processing-instruction(q)]=qt.[text]
for xml path(''),type)
,TotWorkTimeMS=cast(qs.total_worker_time/1000.0
as decimal(12,2))
,AvgWorkTimeMS=cast(qs.total_worker_time/1000.0/qs.execution_count
as decimal(12,2))
,ExecCount=qs.execution_count
,[Calls/Second]=coalesce(qs.execution_count
/datediff(second,qs.creation_time,getdate())
,0)
,AvgElapsedTimeMS=cast(coalesce(qs.total_elapsed_time/1000.0/qs.execution_count,0)
as decimal(12,2))
,MaxLogReads=qs.max_logical_reads
,MaxLogWrites=qs.max_logical_writes
,CacheAgeMins=datediff(minute,qs.creation_time,getdate())
,QueryPlan=qp.query_plan
from sys.dm_exec_query_stats qs
cross apply sys.dm_exec_sql_text(qs.sql_handle) qt
cross apply sys.dm_exec_query_plan(qs.plan_handle) qp
left join sys.databases d on qt.dbid=d.database_id
order by AvgWorkTimeMS desc
And here is the result:

Most Expensive Queries

So the code that produced each of the high-CPU queries is just a click away.

I hope you find all this as useful as I do.

Update Jun26,2010: Check out my next blog entry, where I show how to provide hyperlinks to DDL (CREATE TABLE) code.

Tuesday, June 8, 2010

My Favorite SQL2008 Feature

T-SQL TuesdayThis blog entry is participating in T-SQL Tuesday #007, hosted this month by Jorge Segarra.

You are invited to visit his blog to join the party and read more blogs participating in this month’s theme: Your favorite hot new feature in the SQL2008 R2 (or SQL2008 in general) release.

It certainly was hard to narrow it down to one new feature that really made me excited…

…but here's what I came up with:


For me, the coolest feature of SQL2008 is_member definitely Intellisense… specifically the statement completion aspect. It's a really cool newfilestreamvalue feature!

When I program_name Tan-SQLvariant, Intellisense helps me out by completing the words that I type_id. It's almost like it has_dbaccess E.S.P. original_db_name something… it somehow knows exactly what I want todatetimeoffset say!

When I comparecompressedscalars my productivity between SQL2005 and SQL2008, I am soundex glad that I made the switchoffset to SQL2008. Once I connectionproperty to a serverproperty and point to a database_principal_id, the names of the columns_updated pop up ascii I type the textptr of my queries. And key_guid words are automatically completed too! I no longer have to worry about an error_line index_col my code. No more need to verifysignedbyasymkey that I typed everything correctly. That's the really exciting partition_fragment_id! It's fantastic!

So if you are still using SQL2005, don’t be dense_rank! Act now and make the change_tracking_current_version to SQL2008. Get_filestream_transaction_context update-to-dateadd with the current_request_id technology! You'll be happy you did. Intellisense has_dbaccess made it all worth it.

And you can quotename me on that!